Clustering and Representation Learning
Implemented clustering and dimensionality reduction from scratch, tracing how initialization, soft assignments, and representation change experimental results.
Testing the Assumptions Behind Clusters
I implemented K-means, soft K-means, and PCA from scratch, then trained a linear autoencoder to compare learned and eigendecomposition-based representations. Experiments on wheat-seed measurements and images examined how initialization, cluster count, and assignment softness changed the result.
Farthest-distance initialization and split/merge moves made centroid selection explicit. Sweeping the soft-assignment temperature exposed a practical failure mode: overly diffuse assignments pulled cluster centers together.
What the Experiments Showed
On the 210-sample wheat-seed dataset with seven features, the reported three-cluster runs scored 0.7166 for K-means and 0.6717 for soft K-means. Soft assignments were not automatically an improvement.
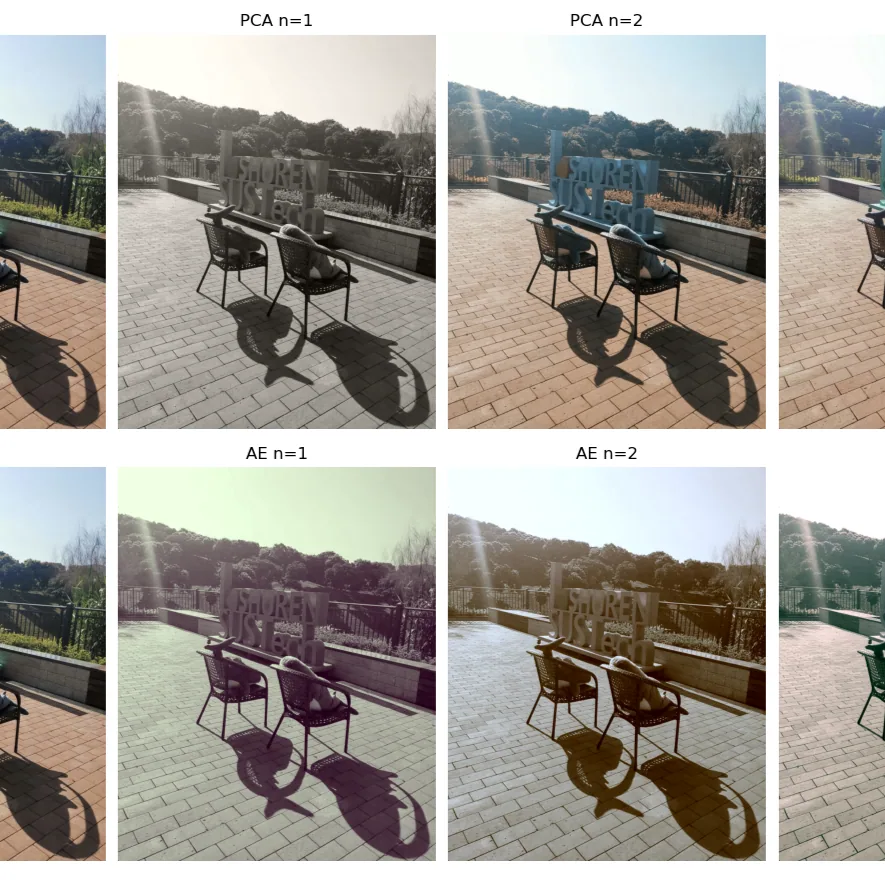
For image reconstruction, PCA and the linear autoencoder produced visually comparable low-dimensional representations. Together, the experiments connected implementation choices to observable cluster structure and reconstruction quality.